The Audience You Refresh Is Not the Audience You Originally Validated
Refreshing a first-party audience segment after initial validation resets the population in ways that invalidate the quality assumptions your team already signed off on.
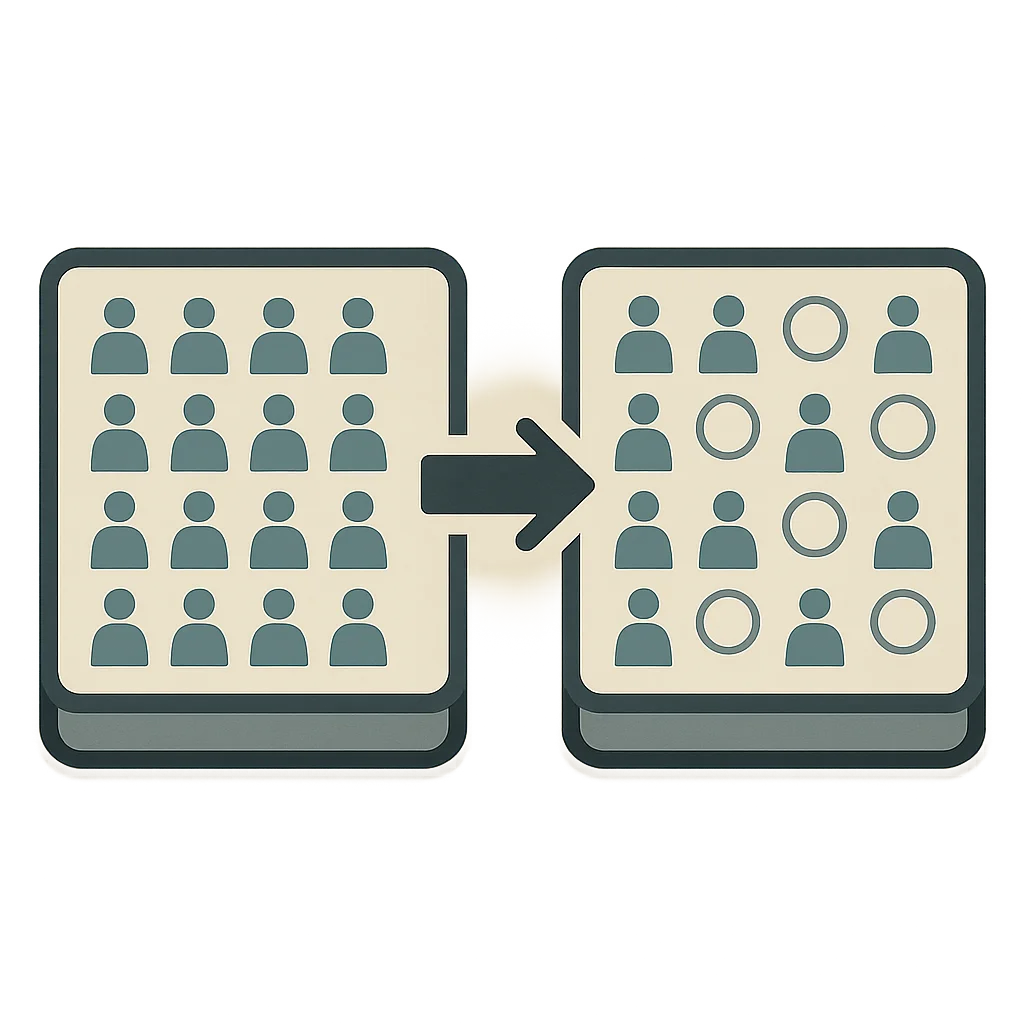
There is a standard workflow in most programmatic operations teams that goes roughly like this: an audience is built, a QA pass confirms it looks right, the campaign launches, and then at some point during the flight the segment gets refreshed to keep the data current. The refresh feels like routine maintenance. It is not.
Every time a first-party audience segment is refreshed, the underlying identity resolution process runs again against whatever state the graph is in at that moment. That process does not know what your validation step approved two weeks ago. It does not preserve the people who passed your original quality check. It produces a resolved population based on current graph state, current match logic, and current input file composition. If any of those three things have changed, and at least one of them almost always has, the audience you are now activating is structurally different from the one you validated.
Why this matters more than it appears
Audience validation in B2B media buying typically involves checking a few specific things: segment size, overlap with known accounts or personas, category distribution, and sometimes a spot-check against a suppression list. The validation is tied to a snapshot. When the segment refreshes, each of those checked properties can shift without triggering any alert, because the refresh itself is not treated as a new activation event requiring sign-off.
The practical consequence is that buyers are often running on a validated label attached to a population that was never validated. The segment name has not changed. The targeting parameters in the DSP have not changed. But the people receiving impressions may reflect a materially different composition than the people your team approved.
Three things that change during a segment refresh
The first is input file composition. If your CRM or CDP is continuously syncing to your onboarding partner, the raw file that seeds the resolution process may have gained new records, lost churned accounts, or updated email addresses that alter which graph nodes get traversed. A refresh that runs after a routine CRM hygiene pass can drop a meaningful portion of the original validated population and replace it with newly onboarded records that have not been reviewed.
The second is graph state. Identity graphs are not static. Device pairings, email-to-cookie linkages, and IP-to-household assignments shift continuously. A person who resolved cleanly to a specific device cluster during your initial validation may resolve to a different cluster, or fail to resolve at all, when the refresh runs. The change is invisible in your standard reporting because the segment size typically stays within a normal-looking range, which masks the fact that the underlying composition has rotated.
The third is match logic versioning. Onboarding and resolution platforms update their matching algorithms and graph weights on schedules that are rarely communicated to buyers. A refresh that runs after a platform-side update may apply different probability thresholds or different fallback rules than the one that produced your validated audience. The segment that comes back looks similar on the surface, because size and category labels are preserved, but the resolved individuals behind those labels may reflect different resolution confidence levels.
What a more defensible refresh practice looks like
The most straightforward structural fix is treating every audience refresh as a lightweight re-validation event rather than an automatic background task. This does not require a full QA cycle every time. It does require establishing a small set of trackable properties that can be compared before and after a refresh runs.
As a starting point, consider tracking three things across refresh cycles. First, segment overlap with your highest-confidence known accounts: if that overlap drops more than a defined threshold between refreshes, flag it for review before the refreshed segment goes live. Second, the distribution across whatever categorical or firmographic signals your validation originally approved: a meaningful shift in distribution is a signal that the resolved population has changed, even if the segment size has not. Third, the timestamp of the last graph update acknowledged by your onboarding partner: if the refresh ran shortly after a graph version change, that warrants a manual check.
None of these checks require custom tooling. They require establishing the comparison baseline during your initial validation, which most teams skip because the initial validation is done once and the expectation is that refreshes preserve it.
The clean room version of this problem
Buyers using data clean rooms for audience co-development run into a version of this issue that is harder to detect. When a clean room query is re-run to generate a refreshed output file, the query logic may be identical, but the data tables inside the environment are updated on their own refresh cadence. If your partner's first-party data inside the clean room has been updated since your original query, the refreshed output reflects a join against a different population than the one that produced your validated segment, even though the query itself has not changed.
Asking your clean room operator to document the data vintage of each table at the time a query runs is a reasonable request, and the answer will tell you whether your refreshed output is comparable to your original validated one or not.
Framing this for internal conversations
Bringing this up inside a team that treats segment refresh as a technical operation rather than a campaign decision can be difficult. The framing that tends to land is not about data quality in the abstract. It is about audit continuity: if your validated audience is the basis for your measurement baseline, and the refresh changes who is in that audience, then your measurement baseline no longer describes your campaign. Any performance conclusion drawn from that baseline is comparing results against a population your team never formally approved.
That is not a technical edge case. It is a workflow gap that sits at the boundary between media operations and data governance, which is exactly why it tends not to get owned clearly by either team.
Assigning explicit ownership of refresh validation, even informally, is a practical first step. The goal is not to slow down campaigns with process overhead. It is to make sure that the audience your team approved and the audience your budget is reaching remain the same population across the full flight.