The Audience You Define by Job Title in a B2B Segment Was Classified by a Data Contributor Whose Taxonomy May Not Match Your Buyer
B2B audience segments built on job title targeting inherit the classification logic of the data contributors who labeled those titles, not your definition of who buys.
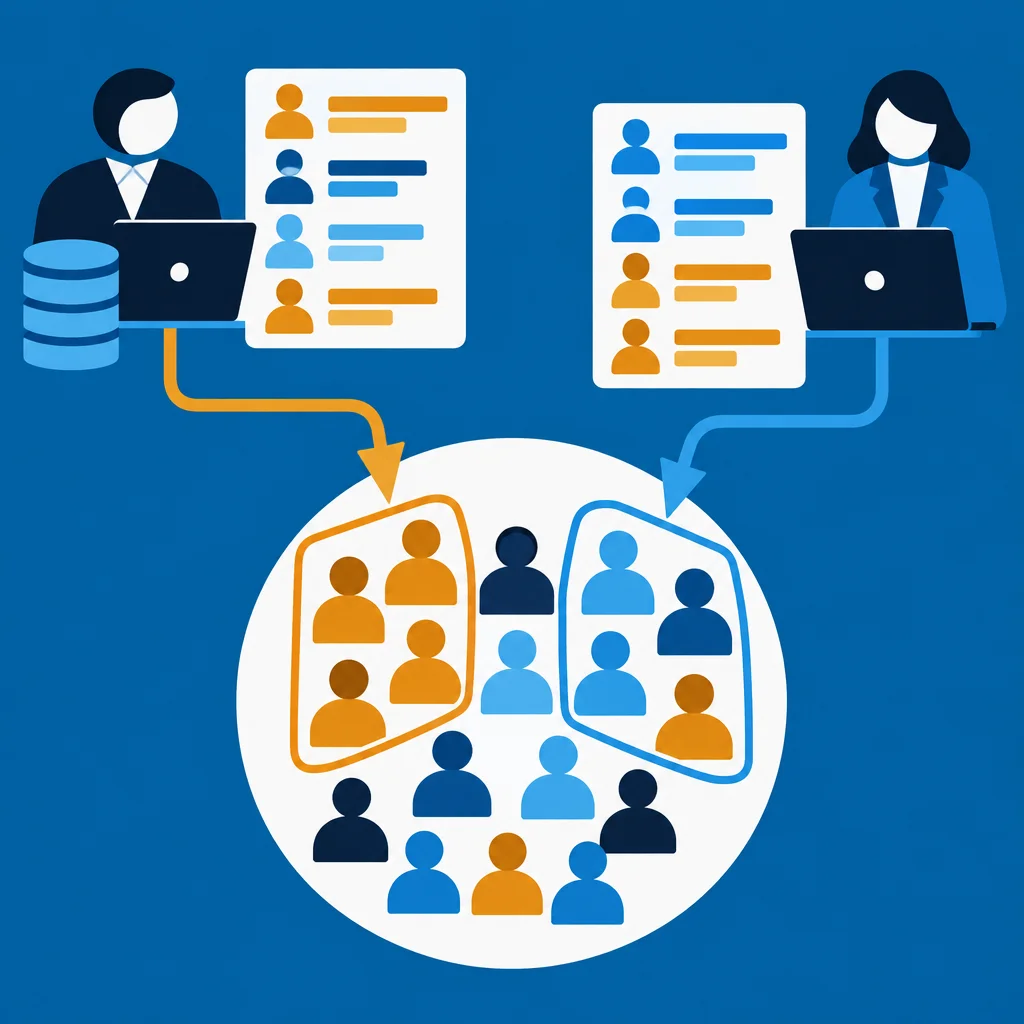
When a media buyer selects a job title segment from a data marketplace or DSP audience library, the assumption underneath that selection is usually straightforward: the people in this segment hold the title I specified, and that title correlates with the buying decision I care about. Both parts of that assumption deserve more scrutiny than most campaign briefs give them.
Where the Title Label Actually Comes From
Job title data inside a B2B audience segment does not originate from a single authoritative source. It is assembled from contributors: HR databases, professional networking platforms, intent data providers, survey-based panels, and business contact vendors. Each contributor classifies titles according to its own schema. One contributor may store a record as "Director of Marketing Operations" while another contributor holding a record for the same person stores it as "Marketing Technology Director." Both are plausible titles for the same individual, but only one might match the keyword logic your segment provider used to build the audience you are buying.
The segment you activate is therefore a reflection of how contributors labeled their records before the data reached you, not a reflection of how your organization defines the role you are trying to reach.
The Taxonomy Problem Is Not Random Noise
It might be tempting to treat title inconsistency as statistical noise that averages out at scale. It does not average out cleanly, because the inconsistency is not random. Certain roles are systematically over-counted or under-counted depending on which contributor types dominate a provider's supply.
For example, consider a hypothetical where your campaign targets procurement decision-makers in mid-size manufacturers. A data contributor whose primary supply comes from a professional networking environment may have strong coverage of people who self-report titles on those platforms, which skews toward industries and seniority levels where platform participation is high. A contributor supplying titles from business contact databases may classify the same procurement function under supply chain or operations titles that your segment query never captured. The people most likely to approve your product category may be absent from your segment not because they do not exist in the graph but because the contributor taxonomy routed them into a bucket your query did not include.
This is a structural gap, not a data quality failure in the traditional sense. The contributing source may have accurate records. The mismatch is between contributor classification logic and your buyer definition.
Why Match Rate Does Not Solve This
A healthy match rate from your CRM onboarding tells you that records resolved against the graph. It does not tell you whether the job titles on those records were classified consistently with the third-party segment you are expanding into. When you use your CRM as a seed to validate a third-party segment, you are checking for identity overlap, not for taxonomic alignment. Two people can share a matched identity node while holding titles that sit in entirely different provider segments.
This distinction matters most when your campaign goal is prospecting beyond your current customer base. Your matched CRM tells you about people who already found you. The third-party segment is supposed to find people like them who have not. If the classification logic differs between how your CRM titles are stored and how the third-party provider labels equivalent roles, your lookalike expansion may be drifting toward roles that look adjacent in the data but are functionally different buyers.
Practical Steps Before You Lock a Segment
Before activating a job title segment, ask the data provider a specific question: what are the top five contributing sources for this segment, and how does each source classify title data? Providers who can answer this question are signaling that they have documented their supply chain. Providers who offer only general descriptions of their data are asking you to trust a black box.
If you have access to a sample or overlap report inside a clean room or preview environment, look at the actual title strings present in the matched population, not just the segment label. A segment sold as "VP and above, Finance" may contain a meaningful share of records where the contributing title is a functional variant your definition would not have included, or may be missing a variant it should include.
It is also worth asking whether the provider normalizes titles before segmentation or uses raw contributor strings. Normalization means the provider has mapped contributor titles to a common taxonomy. That normalization is not neutral: it reflects decisions the provider made about equivalence. Understanding those decisions helps you evaluate whether the provider's normalization aligns with your buyer definition or diverges from it.
Thinking About the Signal Underneath the Title
Job title is a proxy. It is a reasonable proxy, but it is a proxy for something else: decision authority, budget control, functional responsibility, or category relevance, depending on your product. When you treat title as the target rather than the proxy, you make the segment's classification logic do more work than it was designed to do.
One alternative worth considering, particularly for high-value B2B campaigns, is pairing title-based targeting with intent or behavioral signals that are category-specific. A person holding an ambiguous title who is actively researching your product category in documented intent data is a stronger candidate than a person holding your exact target title with no behavioral signal. Combining the two layers does not eliminate the taxonomy problem, but it reduces your dependence on the accuracy of a single contributor's classification decision.
If your campaign is large enough to support it, running a small holdout or sequenced test across two providers with different contributor mixes can surface whether title classification differences are affecting your qualified traffic rate. This is not a formal incrementality test, but it is a practical way to check whether segment composition varies meaningfully across sources selling what appears to be the same audience.
What This Means for How You Report Performance
If your campaign underperforms on qualified lead rate or downstream conversion, the standard diagnostic looks at creative, landing page, bid strategy, and channel mix. Title taxonomy drift rarely appears on that list, but it is a plausible contributor. An audience that looked right on the brief but was classified from contributor logic that does not match your buyer definition will generate impressions against people who are adjacent to your buyer, not your buyer. The CPM looks the same. The click rate may be similar. The qualification drop shows up later in the funnel, where it is harder to trace back to segment composition.
Building a habit of documenting what you understood about a segment's contributor mix at the time of activation gives you a comparison point when you are diagnosing a campaign that did not reach goal. It also gives you a basis for a more informed conversation with your data provider about what changed if a segment performs differently across flights.